
Use the Sample Size Calculator
Overview
The Sample Size Calculator on the experiment page shows how your experiment is progressing toward a reliable result, and helps answer:
-
Is my experiment collecting enough data?
-
How long until I can trust the results?
-
Is the test ready to conclude?
It is an estimate based on the data collected so far, not a guarantee. Read How the forecast is calculated and Limits and caveats before you use it to stop a test.
This feature is based on the methodology used in our public A/B Test Sample Size Calculator, automated so you don't need to manually input your data or recalculate it as the experiment progresses.
Who it is for
The calculator is mostly intended for websites with a high number of conversions on the experiment's main goal. With few conversions per variation, the observed conversion rates and uplift change a lot from day to day, and so does the forecast. On low-traffic websites, treat the forecast as a rough indication only, and plan the test length up front with the public calculator instead.
The three stages
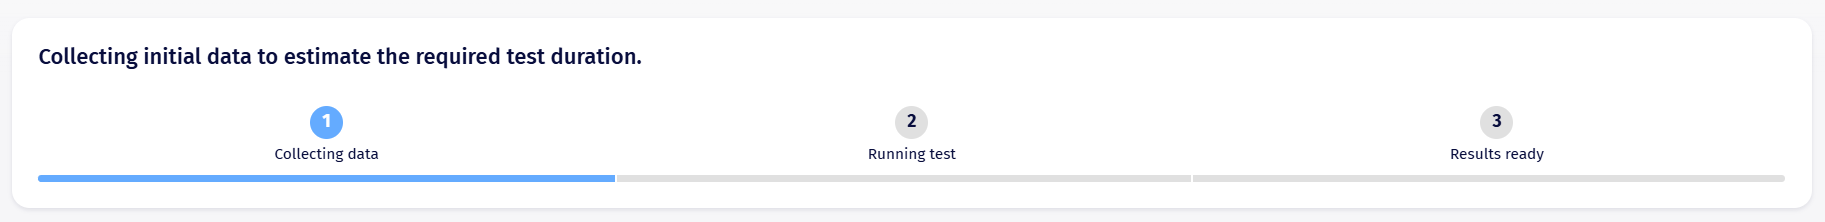
1. Collecting Data
The initial phase. The calculator stays in this stage while the experiment is less than 24 hours old, or until every variation, Control included, reaches:
-
At least 500 users.
-
At least 10 conversions on the main goal (usually Sale).
2. Running Test
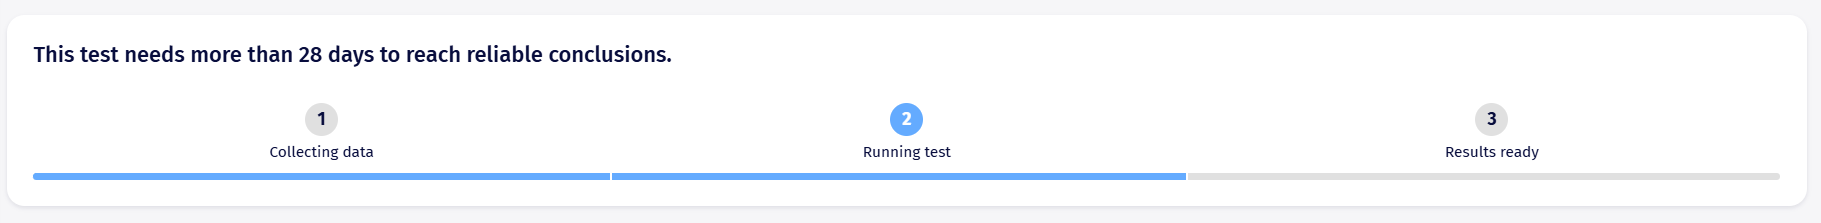
Once the minimum thresholds are met, the calculator shows how many users each variation needs and how many days the experiment should run. The forecast is recalculated every 6 hours, so it changes as new data comes in.
3. Results ready
The experiment reaches this stage when both of these are true:
-
It has been running for at least 7 days. Results are not displayed before then, even if the sample size is already reached.
-
The forecast is under 7 days.
The 7-day minimum makes sure the test covers a full week, so weekday and weekend behaviour are both included.
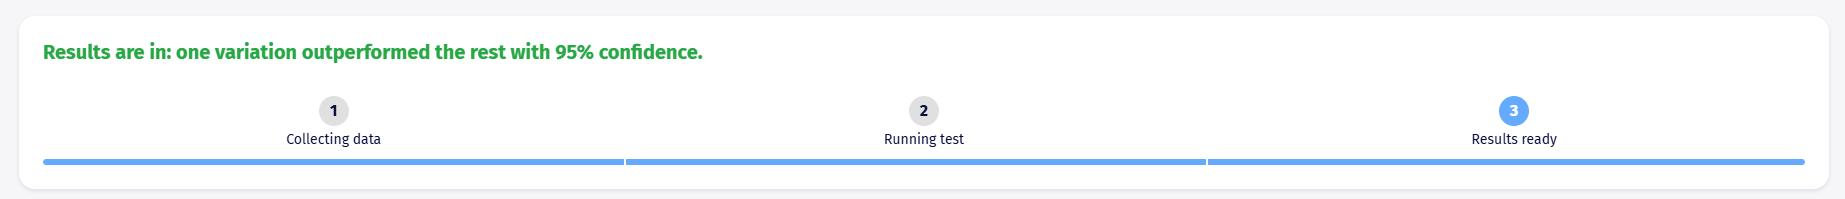
Chance to win does not decide the stage. Once results are ready, it only decides which message you see. The calculator looks at the variations' Chance to win on the main goal, or on the Sale goal if that is higher:
| Chance to win | Message |
|---|---|
95% or above | "Results are in: one variation outperformed the rest with 95% confidence." |
85% to under 95% | "You're on the right track, but not there yet! Refine your hypothesis and run it again." |
Under 85% | "Results are in: no variation reached significance." |
This is the same Chance to win you see in the Chance to win column of the experiment report. It follows your website's Statistical relevance algorithm setting (Bayesian by default): Bayesian or Frequentist uses that result, and Both uses the Frequentist one. See Configure Website Settings.
How the forecast is calculated
The calculator does not update live while you look at the page. Every 6 hours, Explore recalculates the forecast for each running experiment and stores it; the experiment page shows the latest stored result.
Each variation is compared with Control on the experiment's main goal. For each pair, Explore uses two standard sample-size formulas for comparing two conversion rates:
-
The classic formula with pooled variance, which takes the traffic split between the variation and Control into account.
-
Evan Miller's formula.
The page shows the average of the two: the sample size needed per variation, and the number of days to run at your current traffic.
What the forecast is based on
| Input | Value | What it means |
|---|---|---|
Conversion rates | Your experiment's own data | The share of users who reached the main goal, for Control and for each variation, from all the experiment's data so far. This is the Conversion rate column of the report. |
Effect to detect | The variation's uplift over Control on the main goal (10% if the variation is not ahead) | The size of the difference the test is sized to confirm. Uplift is (variation conversion rate − Control conversion rate) ÷ Control conversion rate × 100: for example, 2.2% against 2% is a 10% uplift. In the report, it is the percentage shown next to the variation's Conversion rate on the main goal. If the variation is not ahead of Control, 10% is used instead; if a 10% uplift would push the conversion rate to 100% or more, the calculator aims halfway to 100% instead. For bounce goals, the uplift is counted on visitors who did not bounce. |
Confidence level | The main goal's Chance to win, if it is above 50%; otherwise 95% | The level of certainty the sample size is calculated for: the higher it is, the more users are needed. While a variation is ahead (Chance to win above 50%), the calculator uses its current Chance to win on the main goal, up to a maximum of 99.9%. When no variation is ahead (50% or lower), there is no lead to confirm yet, so the calculator uses the standard 95% instead. This only affects the forecast: the Chance to win shown in the report does not change. |
Power | 80% (fixed) | The chance that the test detects the difference, if it is real. |
The forecast always uses the experiment's all-time data, on all devices. The numbers in the report only match it when the report's filters cover the whole period and all devices.
In other words, the forecast answers: "How many users does each variation need to confirm the uplift this experiment is showing, at the confidence it has reached, and how many days will that take at your current traffic?"
Because the uplift and the Chance to win come from the results so far, the forecast moves with them, as well as with your conversion rates and traffic. A large uplift early in the test makes the required sample size small, so the forecast can drop quickly; if the uplift then shrinks, the forecast goes up again.
Limits and caveats
Reaching the sample size does not lock in the result. An experiment can reach a relevant sample size with a winning variation, and one week later the results can swap, with Control or another variation ahead.
This can happen because:
-
The forecast uses the uplift observed so far. An early uplift is often larger than the real one, which makes the required sample size look smaller than it is.
-
Visitor behaviour changes over time: campaigns, promotions, seasonality and returning visitors can all move the results.
-
With few conversions, a handful of orders can change which variation is ahead.
To reduce the risk:
-
Decide the test length before you start, and run it for full weeks.
-
Don't stop a test the moment it shows Results ready. Check that the result has stayed stable for several days.
-
Read the full report as well: see Read an Experiment Report and Understand Statistical Significance & SRM.
When the calculator can't run
If your experiment is Paused, Expired, or has 0% traffic allocated to Control, the calculator shows a message explaining that sample size can't be calculated until the experiment is updated.